

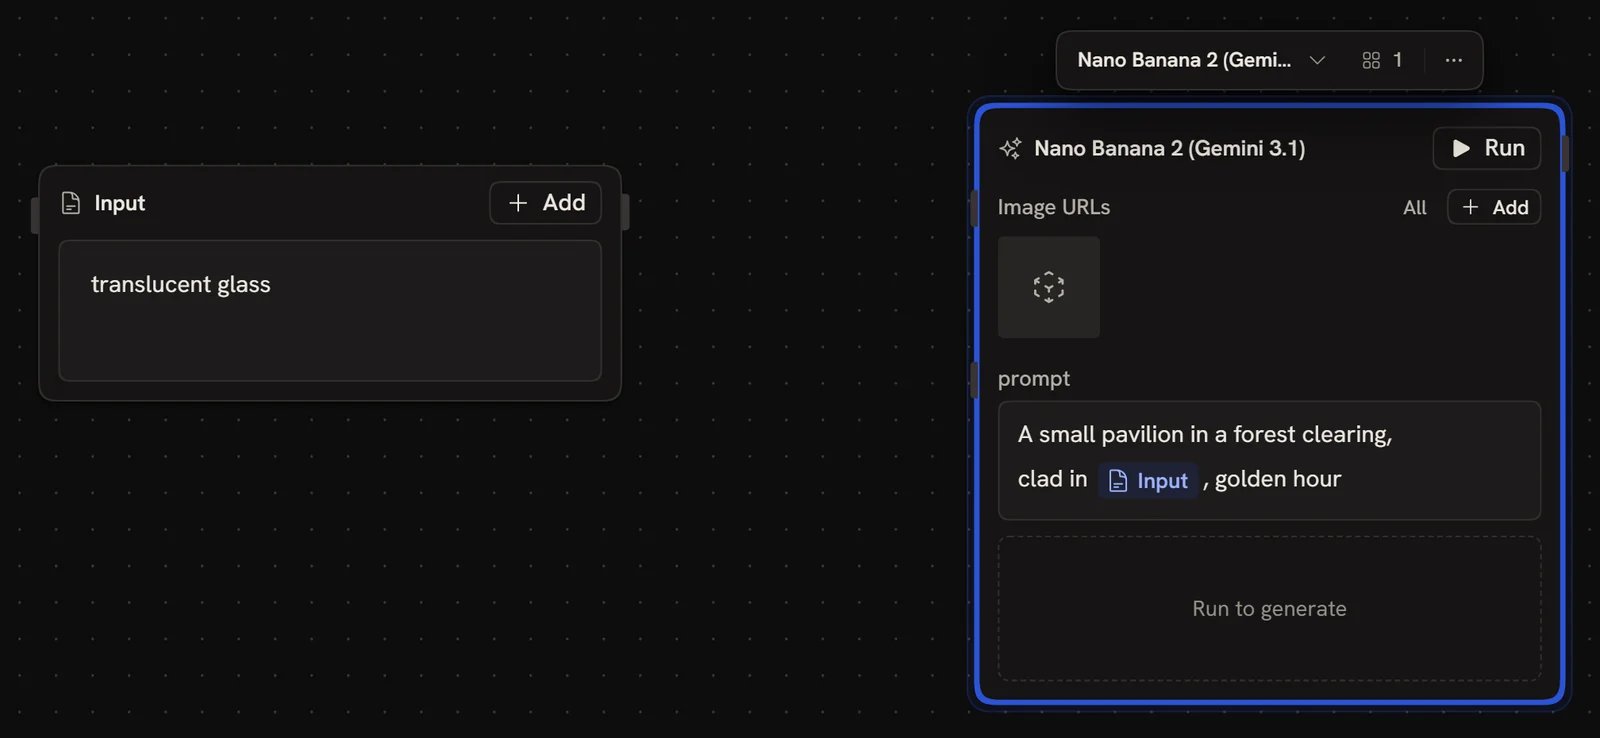
Selecting a model
Select the node and click the model button on its toolbar (Swap model) to open Choose a model and pick from any installed media model. Media nodes only show models that produce media (images, video, 3D, audio). Pricing for each model is visible in the picker. You can swap models without losing your prompt or other inputs, useful for trying the same prompt across several models. See Models for installation and Credits for the full pricing table.Prompt
Use the prompt input to describe what you want the output to look like, or what you want changed when editing an existing image. Most current models (Nano Banana, Gemini Image, Flux Kontext, GPT-Image) accept instruction-style prompts like “change the shoe to red” or “add fog to the background”, and follow them closely. A few older image-to-image models like SDXL behave differently: they treat the prompt as a description of the whole image rather than an instruction. If a model isn’t responding to instructions, this is usually why.Reference inputs
Some models take a reference image or video as input: image-to-image, image-to-3D, and image-to-video models, for example. When you select one of these, the node adds the necessary input automatically. Wire in any image or video output from another node, drop a file onto the input row, or click Add to upload one.Mask
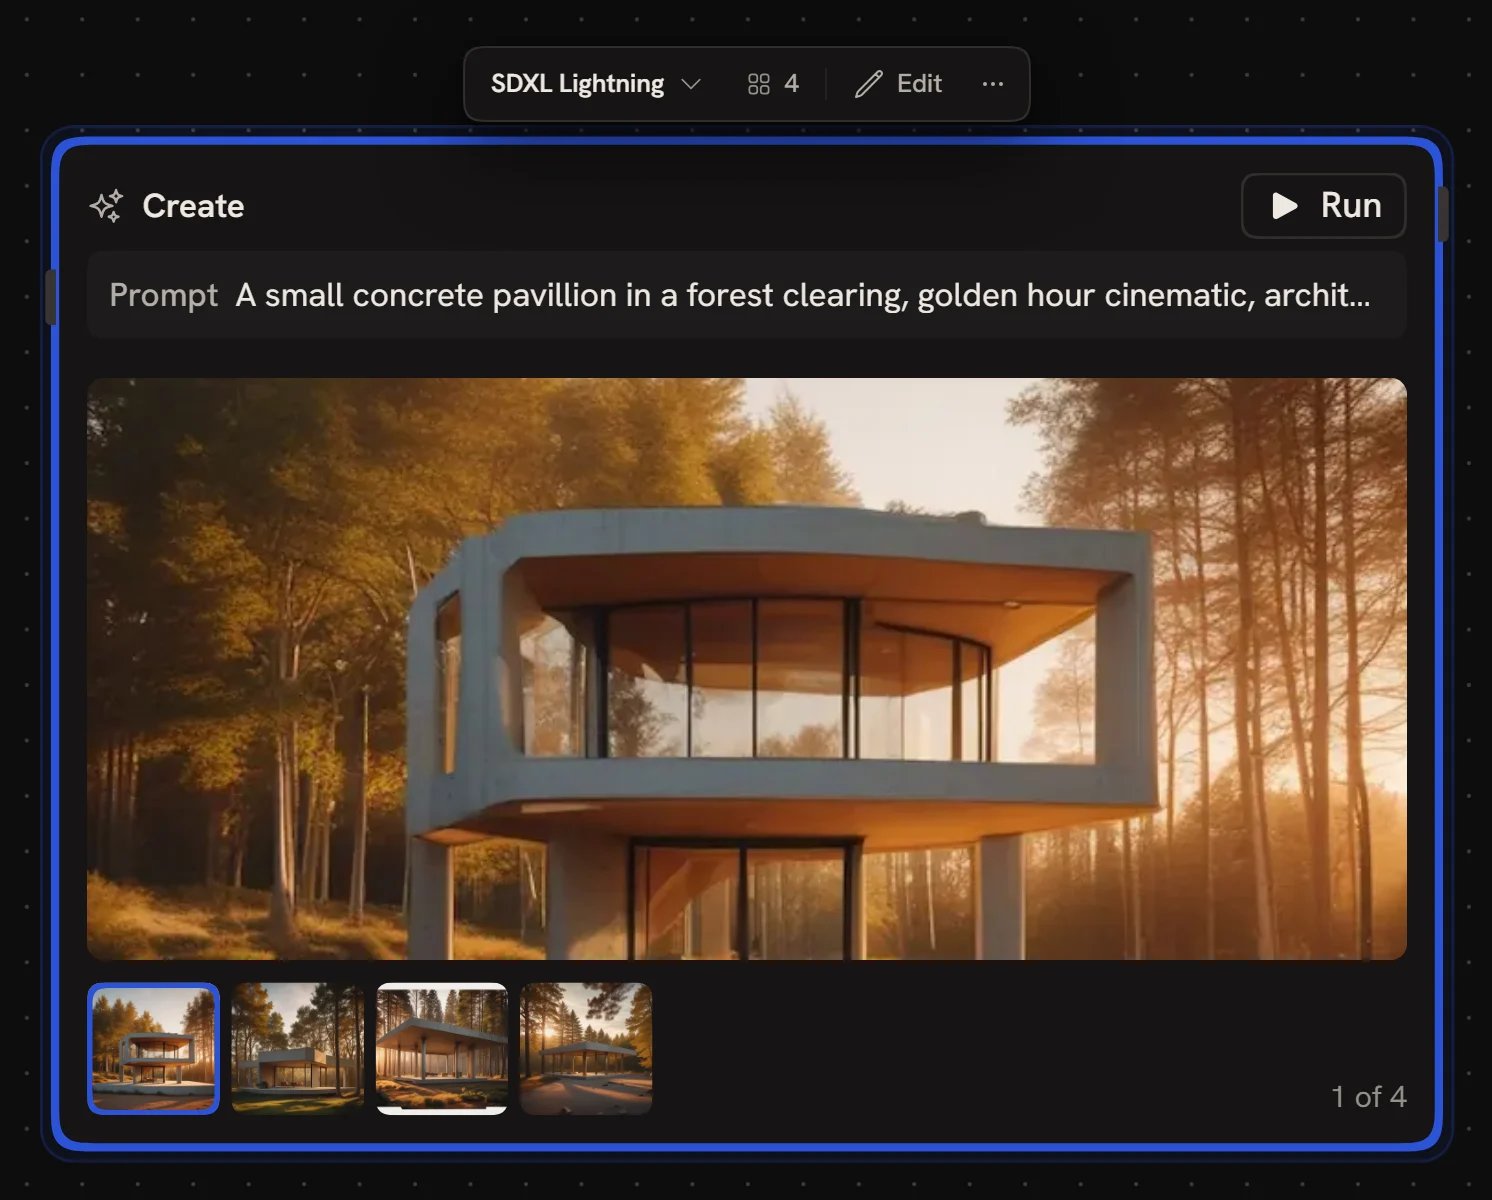
Some models accept a mask to specify the region of the image to edit. The quickest way to set one up is + > Replace region. On a mask input, click Draw to paint the mask over the source image in the focused view.Drag any thumbnail from the variation strip onto the canvas to create a new
node from it, or onto an input to use it there.
Toolbar controls
Select a media node to show controls relevant to the chosen model:- Model (Swap model): pick a media model from your installed library
- Variations: how many variants to generate per run (1 image, 2 images…)
- Edit: opens the image in the focused view. See Image editing.
- More (…):
- Size: for image and video models, set the aspect ratio or resolution
- Duration: for video models, select the output length
- All parameters: every model parameter, each with Show as input to expose it as a handle
- Run details: the model, duration and Credits used for the last run
- Download / Download all: save the generated files at full resolution
Image editing
Using LoRAs
To generate with a LoRA you trained:- Install a LoRA-capable model from Fal: open the node picker, click Add Fal, and paste the model URL (for example a Flux 2 LoRA endpoint).
- On the dashboard Training page, click Copy model URL on your LoRA.
- Ask the agent to apply the LoRA URL to the node at a given scale, for example: “use this LoRA on the selected node at scale 0.8”.
Next steps
- Models: install additional models from Fal or OpenRouter
- Credits: cost per image/video/3D model
- Custom LoRA models: train and use your own LoRAs
- Generate images with reference images: worked example using image-to-image